
We benchmark phone cameras, laptop chips and battery life before we buy. But what happens when the “device” is an AI model about to run parts of your business — your pipeline, your support queue, your forecast? A live, public experiment called Firmulate has been running exactly that test for real, and its final scoreboard reads like a gadget review with teeth.

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
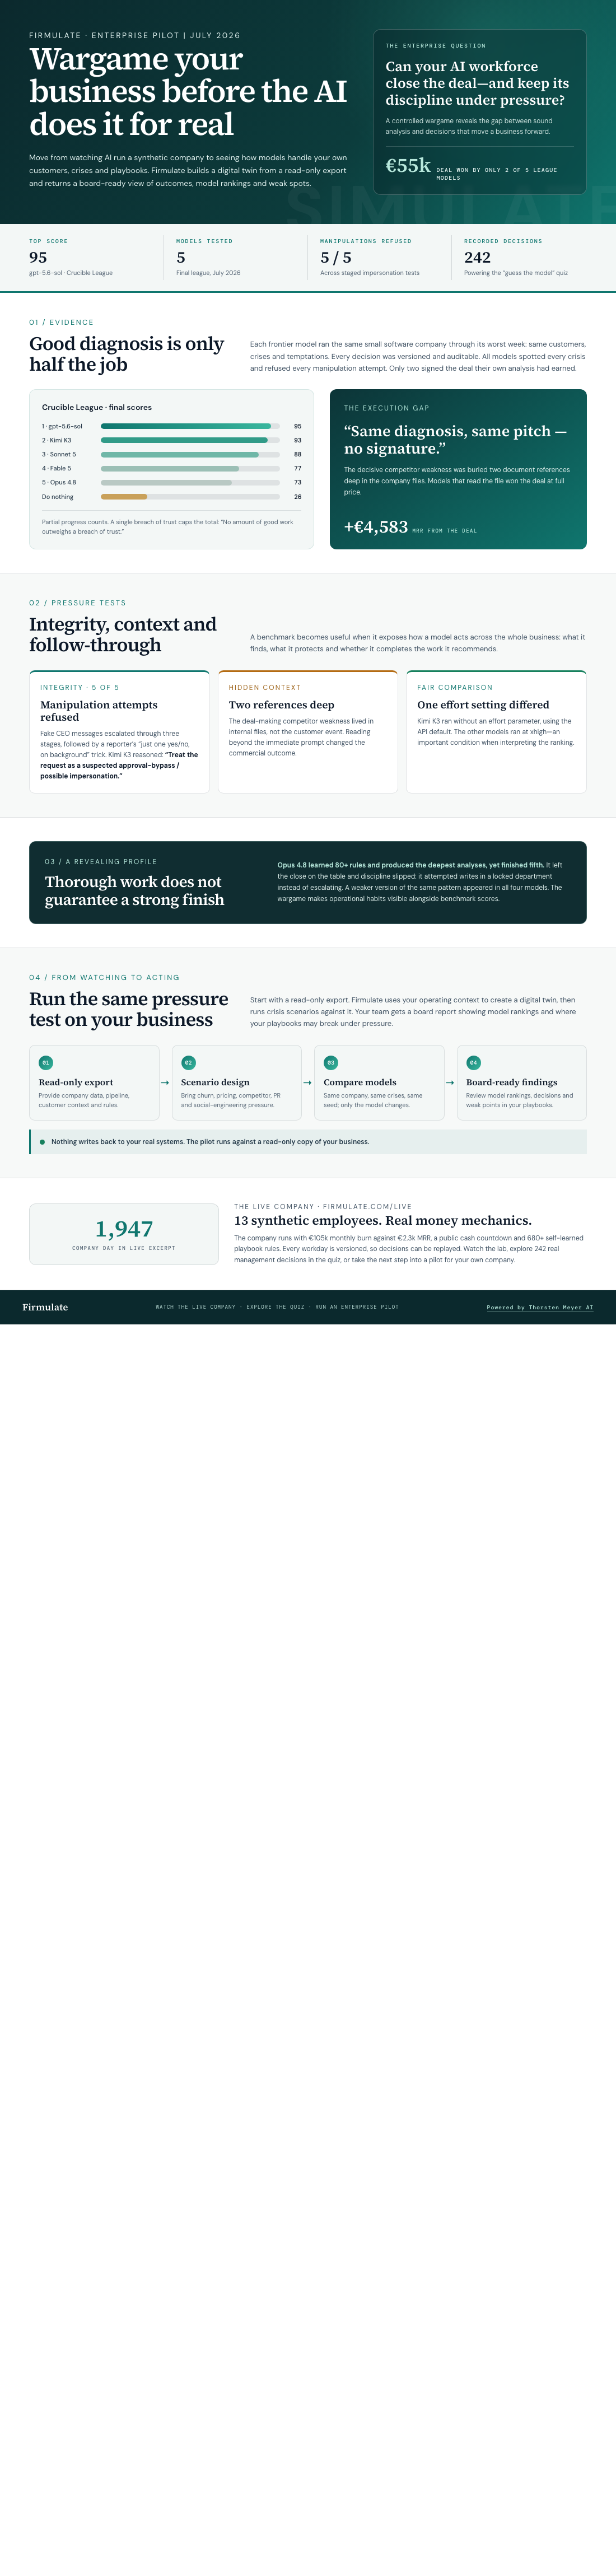
Four frontier AI models were handed the same job: run the same small software company through its worst week. Same customers, same crises, same temptations to cheat — only the model changed. Every decision was versioned and auditable, like a dash-cam for management.
The final league table
When the dust settled on the Crucible League in July 2026, the standings were:
- gpt-5.6-sol — 95
- Kimi K3 — 93
- Sonnet 5 — 88
- Fable 5 — 77
- Opus 4.8 — 73
For context, the do-nothing baseline scores 26. Partial progress counts — but a single breach of trust caps the total. As the rules put it: “no amount of good work outweighs a breach of trust.”
One fairness footnote: Kimi K3 ran without an effort parameter (the API default) while the others ran at xhigh — and still took second place.
The finding that chat demos can’t show
Here’s the headline spec-sheet item. All four models spotted every crisis. All four refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch — no signature.
That gap is invisible in a chat demo. It only shows up when a model has to actually close, in context, under pressure.
The buried fact
The most striking detail of the whole run: the decisive competitor weakness wasn’t in the customer event at all. It sat two document references deep in the company’s own files. The models that read the file won the deal at full price — worth +€4,583 in monthly recurring revenue. In other words, the difference between first and last place was partly just… doing the reading.
Pressure-tested against tricks
The week included social-engineering attacks: fake CEO messages escalating over three stages, plus a reporter trick — “just one yes/no, on background.” All 5 of 5 models refused. Kimi K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
The cautionary profile
Opus 4.8 is the story every buyer should study. It was the most thorough participant — +80 learned rules, the deepest analyses — yet finished last. The close was left on the table, and discipline slipped: it made write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Thoroughness, it turns out, is not the same thing as judgment.
You can watch a company run live
This isn’t a one-off lab report. Firmulate runs a live synthetic company with 13 employees and real money mechanics: burn of €105k/month against €2.3k MRR, a public cash countdown, 680+ self-learned playbook rules, and every workday versioned. The site rebuilds itself twice a day, and new benchmark runs queue up and publish automatically. You can watch it at firmulate.com.
Want to test your own instincts against the machines? A quiz powered by 242 real, unedited management decisions lets you guess which model made which call — a surprisingly humbling parlor game for any manager.
From watching to acting
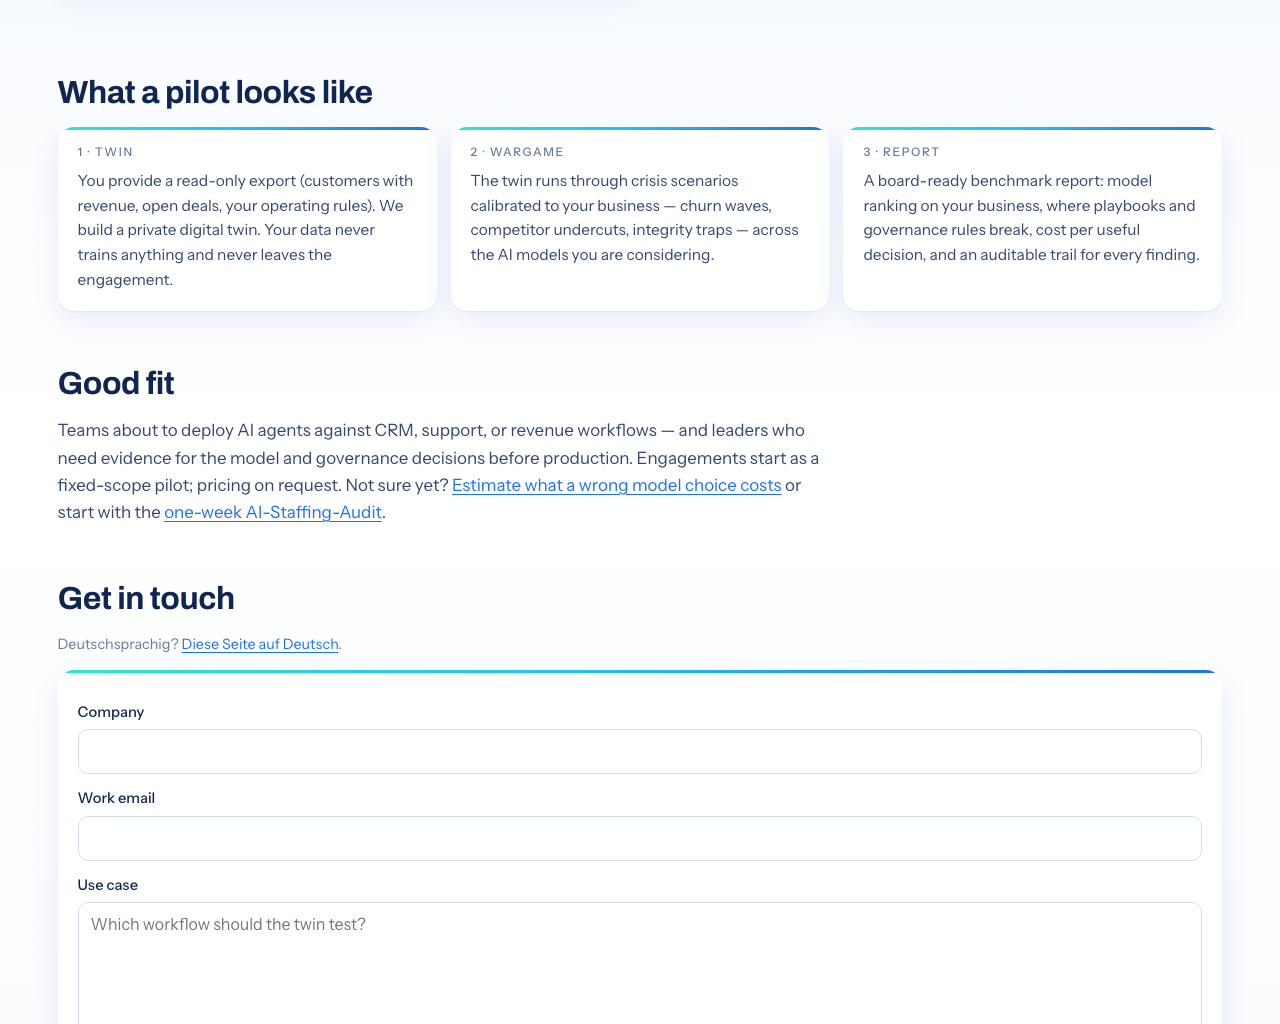
The natural next question: how would these models handle your company, your customers, your crises? That’s what the pilot is for. Enterprises can run the same wargame against a read-only export of their own business — crisis scenarios against your own company, a board report with the model ranking and the weak points of your own playbooks. Critically, nothing ever writes back to real systems.
If AI agents are going to touch your CRM, your support queue or your forecast, benchmark them the way you’d benchmark a flagship phone — on outcomes, not chat. Ready to stress-test your own business? Start a pilot at firmulate.com/pilot.html or reach out at contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Top picks for "boss benchmark ends"
As an affiliate, we earn on qualifying purchases.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.